
Options for Extract Part
This feature lets you extract data selectively by choosing only the areas you want. Try it when you want to improve the structure and accuracy of your extracted data.
During Extract Part, you can use the extraction options in the panel to specify exactly what data to extract from the selected area.
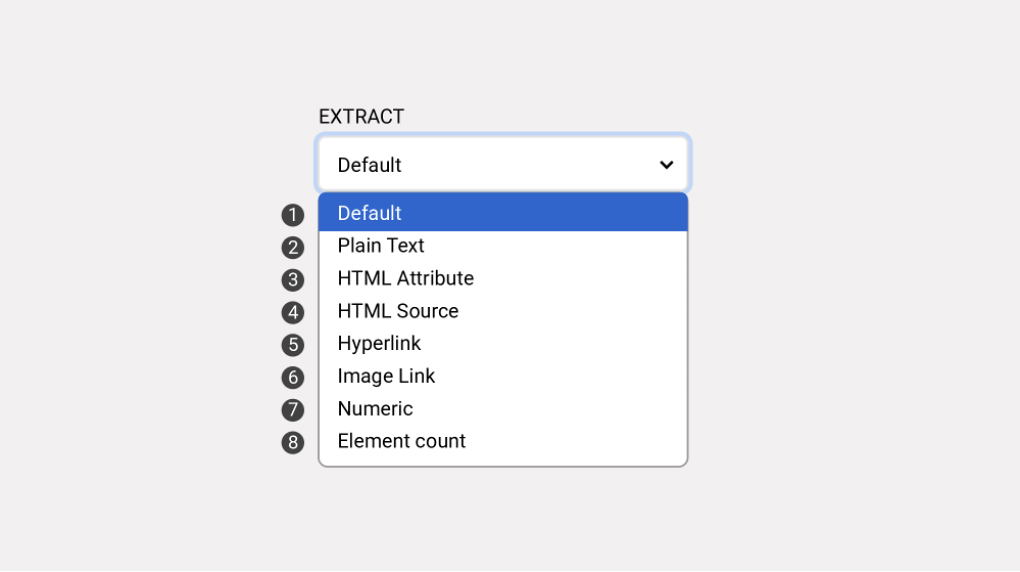
Extraction Options
➊ Default: Extracts provided information as-is, including text, image URLs, hyperlinks, etc. The default option is sufficient for most cases.
➋ Plain Text: Extracts text only, excluding links or image URLs.
➌ HTML Attribute: Extracts values from element attributes. Useful when image paths or product information are stored in attributes. Requires basic development knowledge to use effectively.
➍ HTML Source: Extracts the selected element's HTML code as-is. Used when developers need to process the source later.
➎ Hyperlink: Extracts only hyperlinks attached to text or images.
➏ Image Link: Extracts only image URLs.
❼ Numeric: Extracts only numbers from the selected area.
❽ Element Count: Returns the number of selected elements as a number.
Last updated
Was this helpful?